One hallucinated data point can erase months of client trust – and take a renewal with it. For digital marketing agencies running AI-assisted reporting, that risk is real every single time an LLM touches a client deliverable.
LLMs can speed up analysis and narrative generation dramatically. But without knowledge grounding, evaluation loops, and human approvals, they invent stats, misattribute sources, and quietly amplify errors across every report you send.
This guide walks through a governed workflow built for agency reporting realities. You’ll get concrete mitigation patterns – from retrieval augmented generation to automated fact checks to reviewer thresholds – mapped to the client KPI accuracy your contracts depend on.
Here’s what we cover:
- Why hallucinations happen and why enterprise controls differ from basic prompting tips
- The five-layer mitigation stack agencies actually need
- A step-by-step rollout with tooling, KPIs, and accuracy SLAs
- ROI comparison: manual QA vs. governed automation across 10 clients
- A real agency outcome you can replicate in 30 days
Why LLMs Hallucinate in Enterprise Reporting Contexts
Hallucinations are not random bugs. They follow predictable patterns, and understanding those patterns is the first step toward controlling them at scale.
The Root Causes
Incomplete context is the most common trigger. When an LLM generates a performance summary without access to the actual GA4 or Ads data, it fills gaps with plausible-sounding fabrications. The model does not know it is wrong.
Outdated training knowledge compounds the problem. An LLM trained before your client’s campaign launched cannot know their current benchmarks. It will substitute industry averages – often incorrectly labeled as client-specific results.
Other common causes include:
- Ambiguous prompts that leave room for interpretation
- No evaluation loop to catch factual errors before delivery
- Missing source attribution that would expose unsupported claims
- Lack of policy enforcement on output format and content boundaries
Why Enterprise Governance Is Different
Consumer AI tools can afford occasional errors. Enterprise reporting cannot. Your clients measure you against their own data. A wrong number in a monthly SEO report is not a minor glitch – it is a credibility problem.
Agencies face a distinct set of governance requirements that generic AI hallucination mitigation guides rarely address:
- Auditability – clients and compliance teams need to trace every insight back to a source
- Data lineage – outputs must connect to verified platform data, not model memory
- Brand safety – white-label reports carry your agency’s name and your client’s brand
- Compliance – PII handling, contractual accuracy commitments, and retention policies apply
- Scale – controls must work across 10, 50, or 200 client accounts without proportional headcount growth
The good news: a governed mitigation stack addresses all five. And it does not require a data science team to deploy.
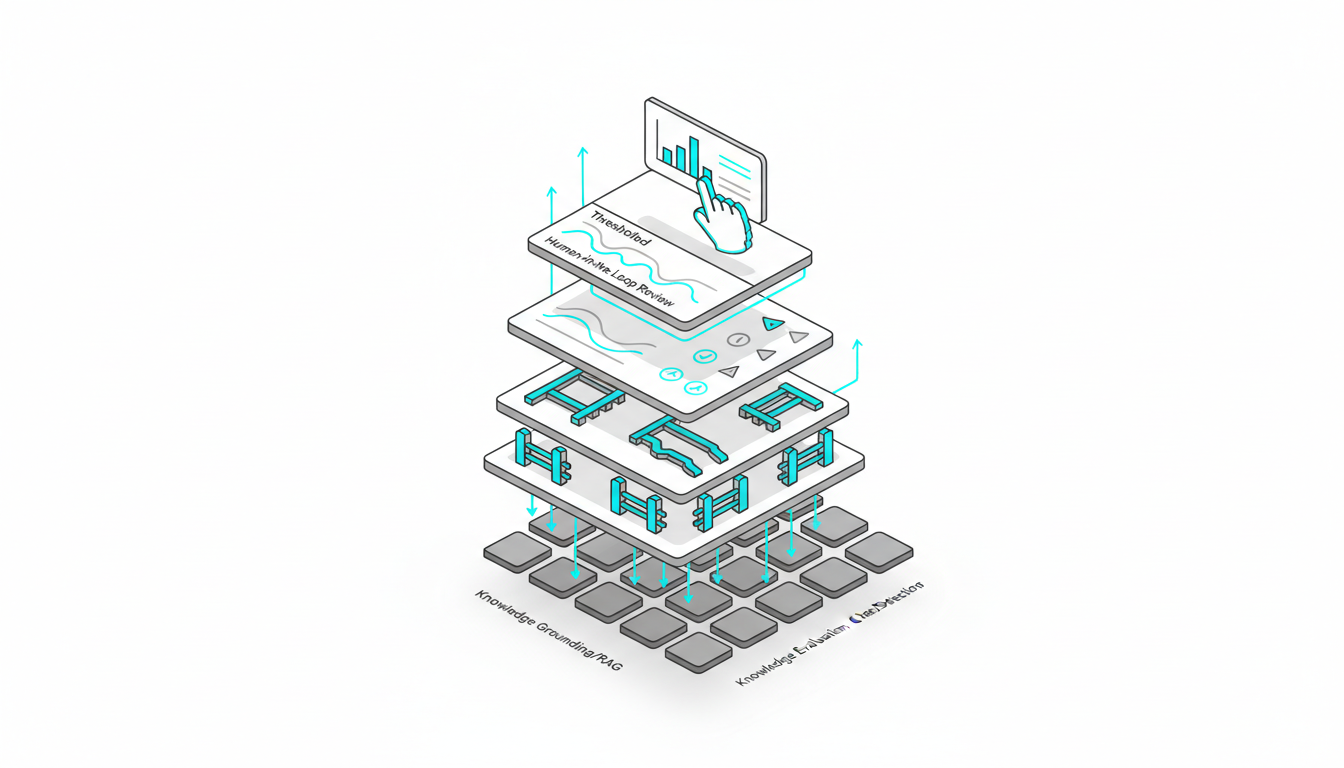
The Five-Layer Mitigation Stack for Agency Reporting
Effective LLM hallucination prevention in enterprise reporting combines five complementary controls. Each layer catches what the others miss. Together, they create a defensible accuracy standard you can put in a client contract.
Layer 1: Knowledge Grounding with RAG
Retrieval augmented generation (RAG) connects your LLM to authoritative data sources before it generates any output. Instead of relying on training knowledge, the model pulls current numbers from GA4, Google Ads, Search Console, or your SEO tools – then builds its narrative around those verified figures.
For agency reporting, this means your monthly SEO summary cites actual crawl data and ranking movements, not approximations. Your PPC wrap references real spend and conversion figures from the ad platform, not industry benchmarks substituted for missing context.
RAG is the single highest-impact change you can make. It eliminates the most common hallucination trigger – missing context – before the model ever starts writing. View integrations to see which data sources connect directly to your reporting workflow.
Layer 2: Enterprise AI Guardrails
Enterprise AI guardrails are policy-based filters applied to inputs and outputs. They define what the model can and cannot say, how it must format claims, and what data it is permitted to reference.
For agency use cases, guardrails typically cover:
- PII redaction before data enters the model
- Brand voice and style constraints on generated copy
- Numeric range checks – flag any figure that falls outside expected variance
- Source citation requirements – no claim without a linked data point
- Competitor mention policies aligned to client preferences
Guardrails do not replace evaluation. They prevent a class of errors from reaching the evaluation stage at all.
Watch this video about Best AI Hallucination Mitigation for Enterprise:
Layer 3: Automated Evaluation and Fact-Checking
AI fact checking automation runs every generated output against your source-of-truth data before any human sees it. Think of it as a QA script that compares the LLM’s claims to the actual platform numbers.
A basic evaluation scorecard for agency reporting tracks:
- Factual accuracy rate – percentage of numeric claims matching source data within an accepted tolerance
- Attribution coverage – percentage of claims with a traceable source citation
- Format compliance – does the output meet template and style requirements
- Anomaly flags – claims that fall outside statistical norms for this client’s history
Evaluation scripts can run automatically on every report draft. Outputs that pass all thresholds move to delivery. Outputs that fail route to a human reviewer queue.
Layer 4: Observability and Drift Detection
Observability for LLMs means monitoring model behavior over time, not just at the moment of generation. Models drift. Data pipelines change. A report that passed evaluation in March may fail in May if an integration breaks or a prompt template becomes stale.
Practical observability for agency teams includes:
- Automated alerts when factual accuracy rates drop below your SLA threshold
- Drift detection comparing current output patterns to a baseline
- Feedback loops that log reviewer corrections and feed them back into prompt refinement
- Change logs tracking template versions, prompt updates, and data source modifications
Layer 5: Human-in-the-Loop Review
Human-in-the-loop review is not a fallback for when automation fails. It is a designed checkpoint that handles edge cases no automated system catches reliably.
The key is threshold-based routing. You do not need a human to approve every report. You need humans to review the reports that fail evaluation criteria or exceed variance thresholds. That distinction is what makes HITL scalable.
A well-designed reviewer queue shows the account manager exactly which claims triggered a flag, which source data contradicts the output, and what correction is needed. Review time drops from 30 minutes per report to under 5 minutes.
Implementation Roadmap: From Pilot to Scale
The fastest path to a governed reporting workflow is a phased rollout. Start narrow, prove accuracy, then replicate across your client base.
Step-by-Step Rollout
- Pilot one report type – choose your highest-volume or highest-risk report (monthly SEO summary is a common starting point)
- Define your accuracy SLA – set a target factual accuracy rate (98% is achievable with RAG + evaluation) and a maximum review cycle time
- Connect your data sources – link GA4, Google Ads, Search Console, and your SEO tools as authoritative grounding sources
- Build evaluation scripts – write automated checks that compare generated claims against source data for your pilot report type
- Set reviewer thresholds – define which failure conditions route to human review vs. auto-approve
- Run the pilot for 30 days – track factual accuracy rate, time-to-approve, and reviewer load
- Refine and replicate – once KPIs meet SLA targets, apply the same template to additional report types and clients
The Automate Your Reports workflow in Reportz maps directly to this rollout. Source-linked dashboards handle grounding. White-label exports carry attribution through to client delivery. Setup takes under three minutes per dashboard.
Tooling Map for Agency Stacks
A governed reporting workflow connects several tool categories. Here is how they align to mitigation layers:
- Data connectors (GA4, Google Ads, Search Console, SEO platforms) – handle RAG grounding
- Dashboard software (Reportz) – consolidates sources, applies templates, generates white-label outputs
- Evaluation scripts – compare outputs to source data, score claims, flag anomalies
- Review workflow – routes flagged reports to account managers with context for fast correction
- Audit trail – logs every version, correction, and approval for compliance and client transparency
KPIs to Track from Day One
Measuring the right things early tells you whether your mitigation stack is working – and gives you the evidence to expand the program.
- Factual accuracy rate – target 98%+ against source-of-truth metrics
- Time-to-approve – how long from draft to client-ready delivery
- Reviewer load – percentage of reports requiring human intervention
- Incident rate – number of errors reaching client delivery per month
- Client satisfaction score – track CSAT alongside accuracy improvements
ROI: Manual QA vs. Governed Automation
The business case for AI governance for enterprises is not abstract. It comes down to hours saved, errors avoided, and revenue retained.
Consider a 10-client agency running monthly reports manually. A typical account manager spends 30-45 minutes per report on data gathering, cross-checking, and formatting. That is 5-7.5 hours per month in direct QA labor, before counting error correction cycles.
With a governed automation workflow:
- Data gathering drops to near-zero – real-time dashboards pull current figures automatically
- QA time falls by 30-50% – automated evaluation handles routine checks; humans review only flagged outputs
- Error correction cycles shrink – catching issues before delivery eliminates the back-and-forth with clients
- Time saved: 4+ hours per client per month – across 10 clients, that is 40+ hours redirected to billable work
The retained revenue side of the equation matters too. One factual error in a client report rarely ends a relationship immediately. But a pattern of errors – or a single high-visibility mistake – accelerates churn. An accuracy SLA you can demonstrate and defend is a retention tool as much as a quality control measure.
A multi-brand agency that deployed grounded dashboards with reviewer thresholds saw approval time fall 42% within 30 days. Client CSAT rose 11 points in the same period. The investment was a 3-minute setup per dashboard and a one-time evaluation script build.
Ready to run the numbers on your own client base? Start My Free 15-Day Trial Now and validate accuracy against your real data sources – no credit card required.
Prompt Engineering and Model Monitoring Best Practices
Grounding and guardrails do most of the heavy lifting. But prompt engineering best practices and ongoing AI model monitoring and evaluation keep the stack performing as conditions change.
Prompt Engineering for Accuracy
Prompts that reduce hallucination share a few common traits. They provide explicit context (the actual data), constrain the output format, and require source citations for every claim.
Watch this video about enterprise AI guardrails:
High-accuracy prompt patterns for reporting include:
- Provide the source data inline – do not ask the model to recall figures from memory
- Specify output format explicitly – table, bullet summary, narrative paragraph
- Require citation format – “cite the metric name and date range for every numeric claim”
- Set scope boundaries – “use only the data provided; do not introduce external benchmarks unless explicitly asked”
- Include a consistency check instruction – “verify that all figures in your response match the input data”
Ongoing Model Monitoring
AI model monitoring and evaluation is not a one-time setup. It is a continuous process that catches degradation before clients do.
Monthly monitoring tasks for agency teams:
- Run regression tests on a sample of past reports to check for output drift
- Review the evaluation scorecard for any accuracy rate trends below SLA
- Audit reviewer correction logs to identify recurring error patterns
- Update prompt templates when data source formats change
- Refresh grounding sources when client campaigns shift significantly
An AI risk management framework for reporting teams documents these tasks, assigns ownership, and sets escalation paths when accuracy drops. It does not need to be complex – a shared doc with monthly review checkpoints is enough to start.
Enterprise AI Governance Checklist for Reporting
Use this checklist to audit your current workflow and identify gaps before your next client report cycle.
- Data grounding – Are all AI-generated claims sourced from connected platform data, not model memory?
- Source attribution – Does every numeric claim in the output carry a traceable citation?
- Guardrails active – Are PII redaction, brand style, and numeric range checks running on every output?
- Evaluation scripts deployed – Does automated fact-checking run before any human review?
- Reviewer thresholds set – Do you have defined criteria for auto-approve vs. manual review?
- Accuracy SLA documented – Is your target factual accuracy rate written into your workflow and client agreements?
- Audit trail active – Are template versions, corrections, and approvals logged?
- Drift monitoring scheduled – Do you have a monthly review of accuracy trends and output patterns?
- Feedback loop established – Are reviewer corrections feeding back into prompt refinement?
- Templates replicated – Are proven report templates applied consistently across all clients?
If you checked fewer than seven of these, your current workflow has meaningful hallucination exposure. The Learn how Reportz streamlines client reporting overview shows how source-linked dashboards and white-label exports address the grounding, attribution, and template replication items directly.
Frequently Asked Questions
What is the most effective way to reduce AI hallucinations in client reports?
Connecting your LLM to live, authoritative data sources through retrieval augmented generation is the highest-impact single change. It eliminates the most common cause – missing context – before the model generates anything. Pair it with automated evaluation checks and you cover the majority of hallucination risk in production reporting workflows.
How do enterprise AI guardrails differ from basic prompt instructions?
Enterprise AI guardrails are systematic, policy-based controls applied at the infrastructure level. They run on every output regardless of who wrote the prompt. Basic prompt instructions only work when a specific user includes them. Guardrails handle PII redaction, brand constraints, and numeric range checks automatically and consistently across all reports.
How long does it take to set up a governed reporting workflow?
A basic governed dashboard with source-linked data takes under three minutes to configure in a purpose-built reporting tool. Building evaluation scripts and reviewer thresholds for your first report type typically takes a few hours. Most agencies complete a 30-day pilot – including rollout, refinement, and SLA validation – before expanding to additional clients.
What accuracy rate should agencies target for AI-generated reports?
A 98% factual accuracy rate against source-of-truth platform data is an achievable target with RAG grounding and automated evaluation. That figure is specific enough to include in client SLA documentation. Accuracy rates below 95% typically indicate a grounding gap – the model is pulling from memory rather than connected data sources.
How does human-in-the-loop review stay manageable at scale?
Human-in-the-loop review scales when you route only flagged outputs to reviewers, not every report. With well-calibrated evaluation thresholds, 70-80% of reports pass automatically. Reviewers see only the specific claims that failed a check, with the source data alongside for fast correction. Review time per flagged report drops to under five minutes.
Can smaller agencies implement these controls without a data engineering team?
Yes. Modern reporting platforms handle data connectors, template management, and white-label exports without custom engineering. Evaluation scripts for common report types – SEO summaries, PPC wraps, social campaign reports – can be built with basic scripting knowledge or sourced from platform documentation. The governance checklist above gives you a starting point regardless of team size.
Ship Faster, Safer Reports Your Clients Trust
The best AI hallucination mitigation for enterprise reporting is not a single tool or technique. It is a layered workflow: grounded data, automated evaluation, policy guardrails, observability, and human review where it counts.
When those layers work together, you get reports your clients can audit, accuracy rates you can put in a contract, and a QA process that scales without scaling your headcount. The time you save – 4+ hours per client per month – goes back into work that actually grows your agency.
Key takeaways:
- Ground every AI output in live, connected platform data with source attribution
- Run automated evaluation checks before any human touches a draft
- Use guardrails and HITL thresholds to catch edge cases without reviewing every report manually
- Track factual accuracy rate, time-to-approve, and reviewer load from day one
- Pilot on one report type, prove ROI against your SLA, then replicate across clients
Explore the Save Time on Reporting features to see how source-linked dashboards and white-label exports map to each mitigation layer in your current workflow.